RAG

Post Image

Exploring Hierarchical RAG: An Advanced Technique for Robust Information Retrieval

In the ever-evolving landscape of information retrieval and Large Language Models (LLMs), Retrieval-Augmented Generation (RAG) is becoming a de facto mechanism to quickly answer questions across a broad range of topics. However, the responses can often suffer from inaccuracies when they predominantly rely on extracting chunks of information with keyword matching only.Hierarchical RAG (HRAG) is a technique to improve the accuracy and relevance of responses.HRAG builds on traditional RAG by using a to organize and find information at different levels,...

Read
Post Image

Testing RAG Pipelines

In today's world, where Retrieval-Augmented Generation (RAG) pipelines are increasingly integrated into applications, it's more important than ever to thoroughly test these systems.Large Language Models (LLMs) are powerful but not perfect. They can hallucinate—generating information that isn’t in the context—and sometimes provide answers that are irrelevant to the user’s query. These issues, or "smells," can harm the reliability of your application, making it essential to thoroughly test your LLM before and after deployment.As open-source LLMs continue to surge in popularity,...

Read
Post Image

Query Decomposition: Understanding the User's Perspective

While searching for any information on the Internet, it's important to determine whether the results being fetched are relevant to what is being searched for. Most of us use search engines like Google, Bing, Yahoo!, or DuckDuckGo to find answers, but do these search engines always return the same results? Interestingly enough, that is not the case. Let's uncover the mystery behind why the same search term can yield different results across different platforms.For example, if the user is searching...

Read
Post Image

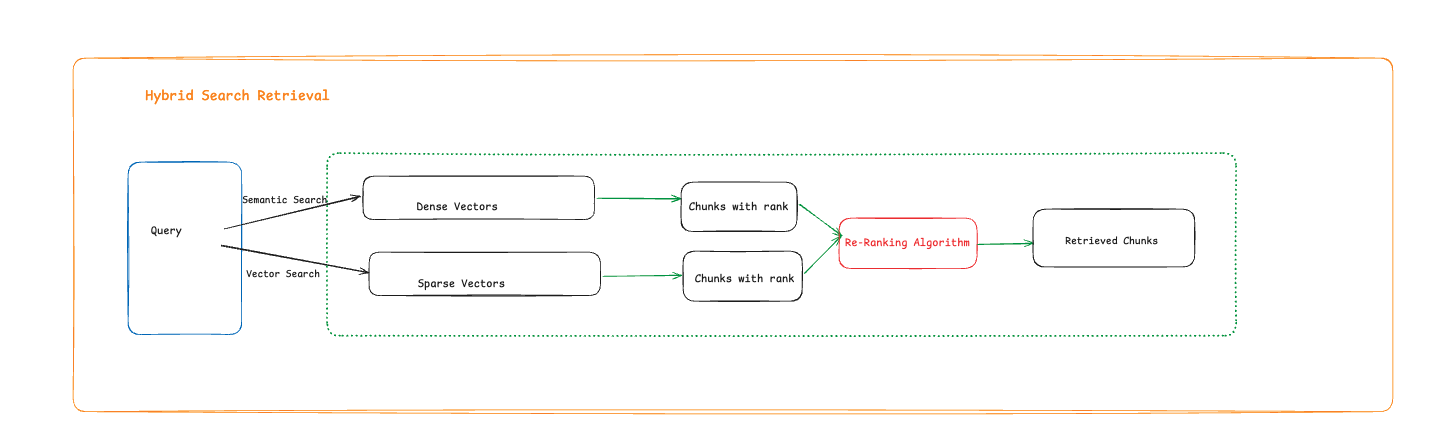
Inside Hybrid Search Retrieval Pipeline: How It Powers RAG Systems

RAG pipelines have been an emerging technology, which leverage LLMs and vector DBs for indexing and retrieving content using conversational capabilities. Here we have talked about how you set up a RAG pipeline and make it operational. This blog deep dives into how to make semantic search more effective in a RAG pipeline. In search, few of the use cases may completely work fine with semantic search, however, some of them may need something that delivers a better output. The problem with...

Read
Post Image

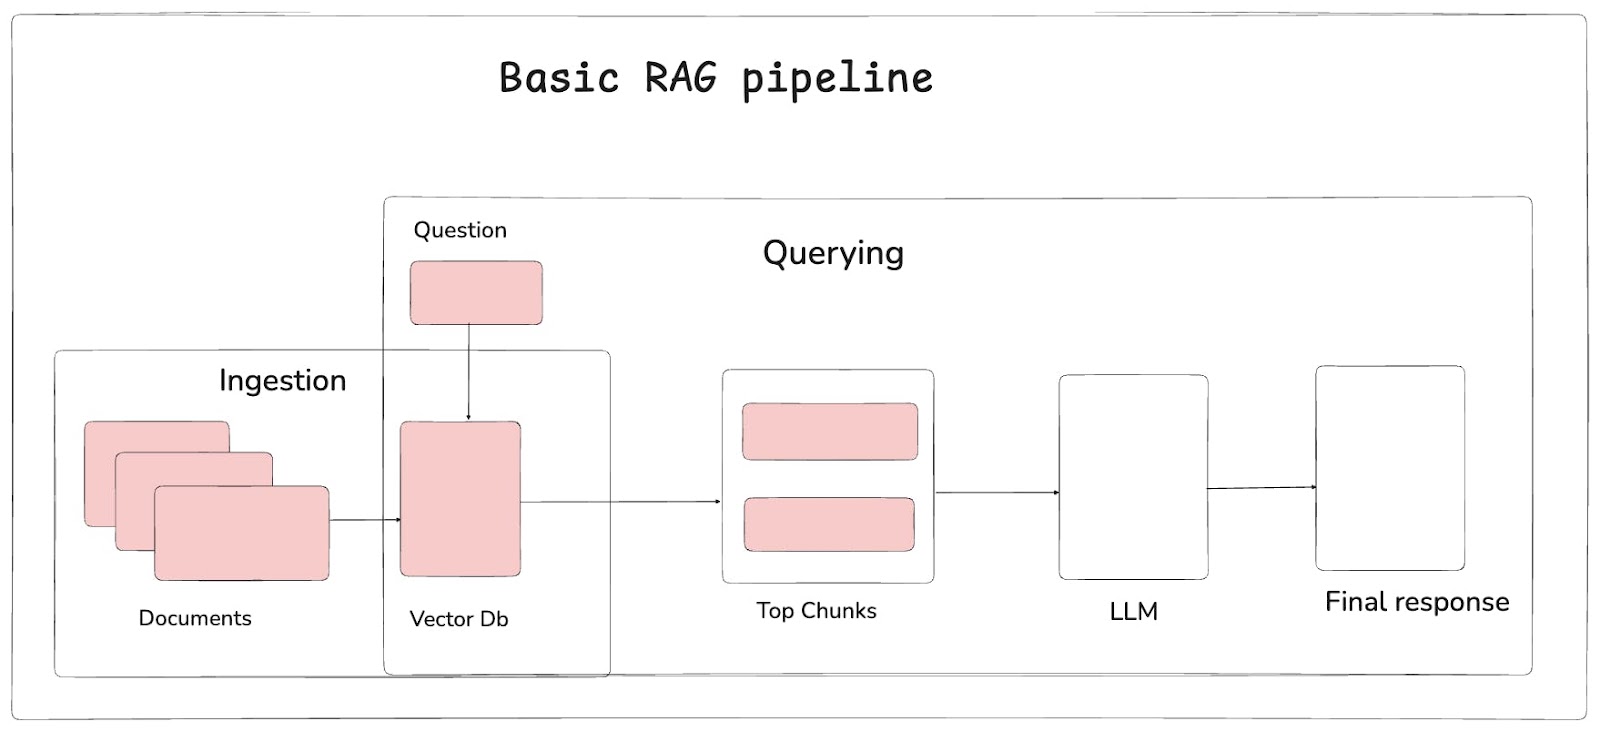
Building Your Own Basic RAG Pipeline with LangChain and Llama3

According to Wikipedia, Retrieval Augmented Generation (RAG) can be defined as a technique that grants generative artificial intelligence models information retrieval capabilities. It modifies interactions with a Large Language Model (LLM) so that the model responds to user queries with reference to a specified set of documents, using this information to augment information drawn from its own vast, static training data. So, what is a RAG pipeline? In simple words, a RAG pipeline retrieves texts from a retriever, asks a...

Read