Apache Spark

Post Image

Prompting Is Architecture: Why Understanding Systems Matters More Than Ever

A Spark story about scale, grain, and why speed makes system awareness non-negotiable.Image generated using ChatGPTRecently, I ran into a Spark job that looked perfectly fine. I used Claude in this case to generate code, which wasSyntactically correctSemantically correctEasy to read and reason aboutThis worked on the sample dataset. Assuming Spark will manage the scale, we pushed it to production. However, on prod, it took more than 3 hours to complete on a 40-node EMR cluster. It was trying to...

Read
Post Image

Fine-Tuning Shuffle Partitions in Apache Spark for Maximum Efficiency

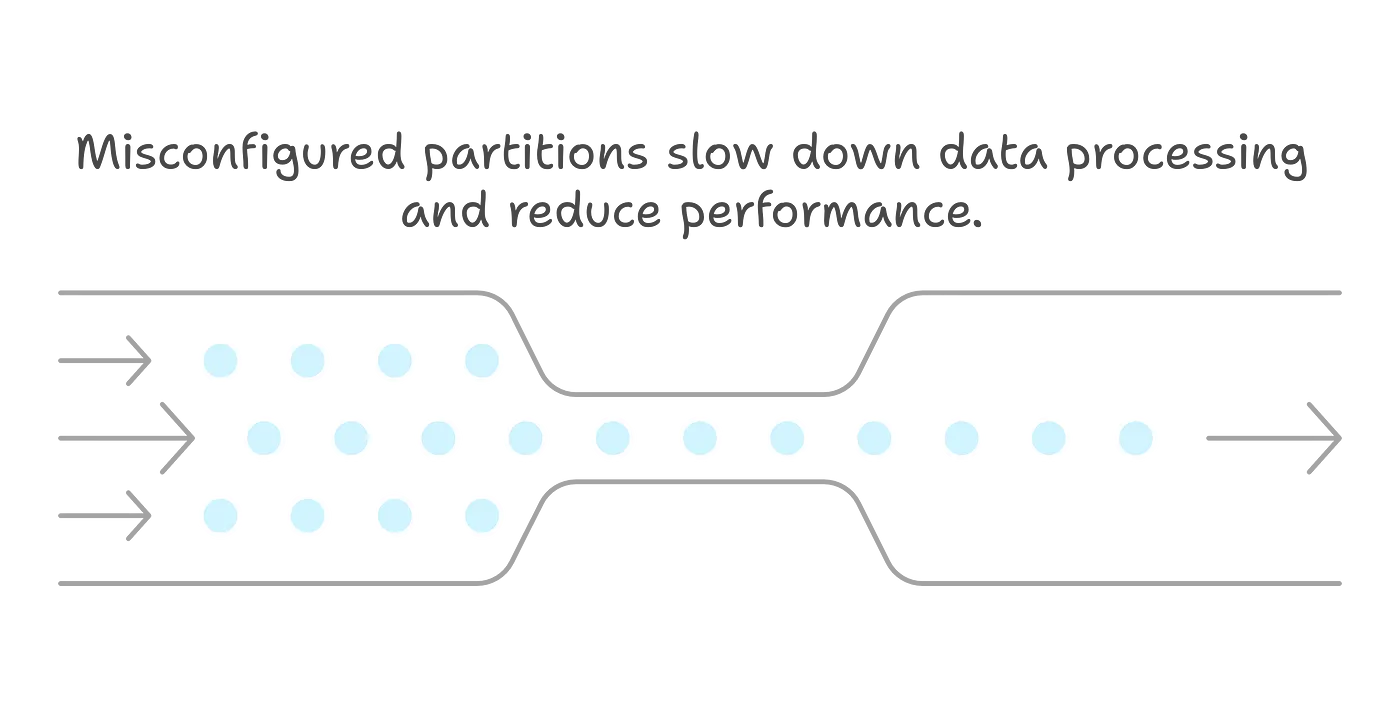
Apache Spark’s shuffle partitions are critical in data processing, especially during operations like joins and aggregations. Properly configuring these partitions is essential for optimizing performance.By default, Spark sets the shuffle partition count to 200. While this may work for small datasets (less than 20 GB), it is usually inadequate for larger data sizes. Besides, who would work with just 20 GB of data on Spark?To optimize performance, it’s crucial to determine the appropriate number of shuffle partitions. Here are some...

Read